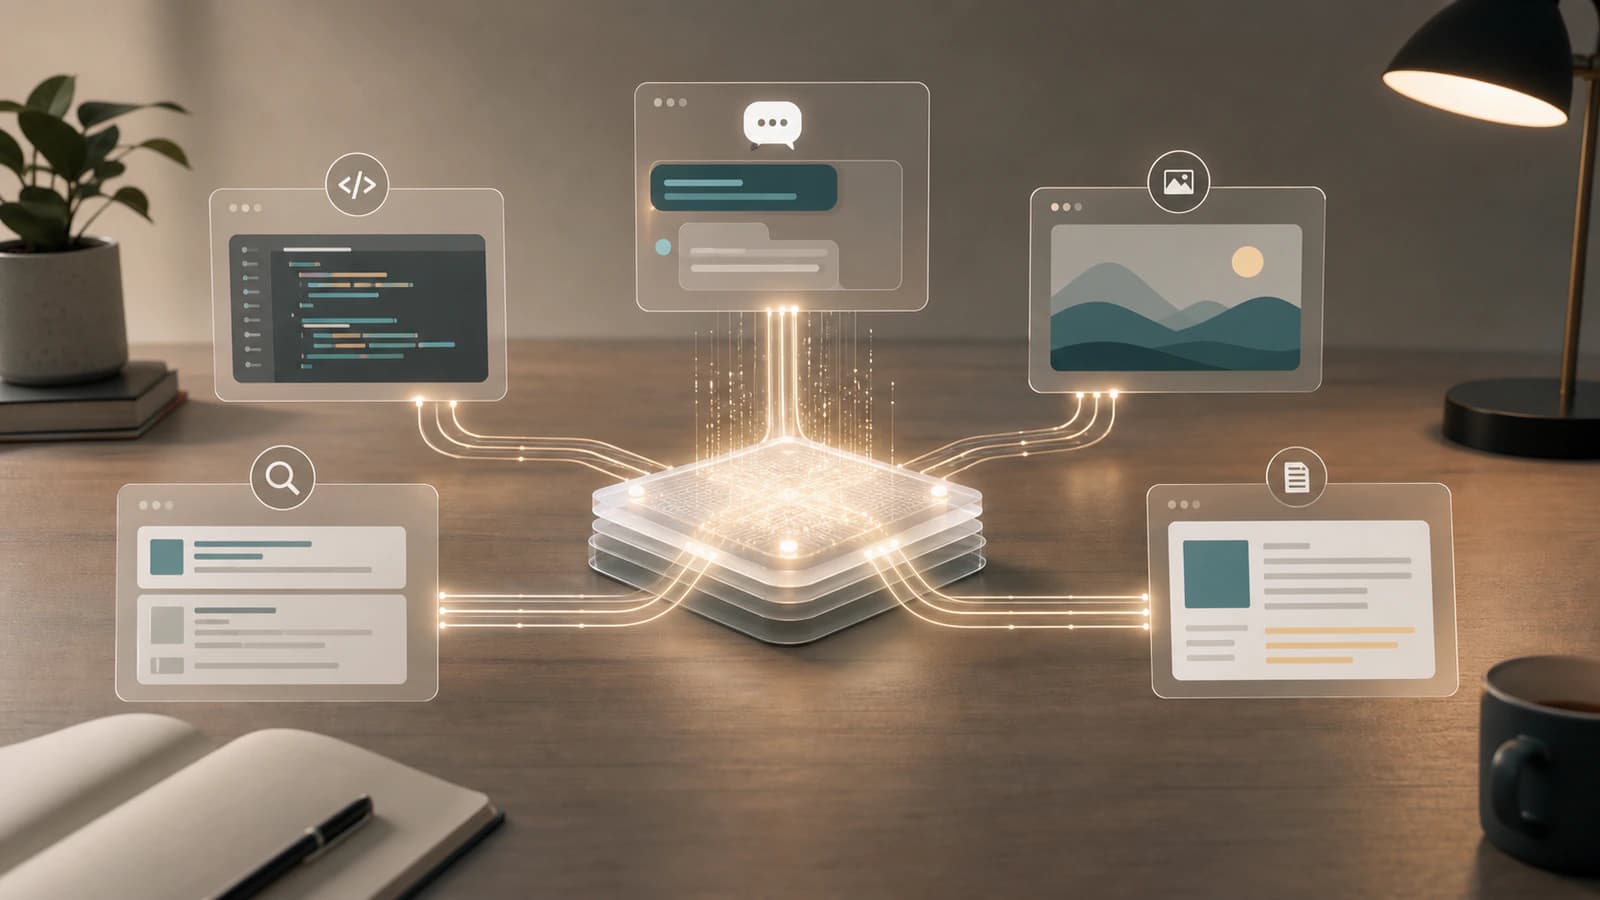
A company wants an assistant to answer product questions. It could train a language model from scratch, or start with a broadly trained model and supply its own product information, instructions and checks. That reusable starting point is the foundation model. Its general capability saves work, while the specific product still depends on what the team builds around it.
That broad starting point does not guarantee success on a specific task. The model has learned patterns from large amounts of data; a useful product still needs instructions, relevant context, evaluation and often tools. This guide explains foundation models as large reusable base models, how they work, why they changed AI development, and where the reuse story needs a careful human hand.
Quick Answer: What Is a Foundation Model?
A foundation model is trained on broad data at scale so it can be adapted to many downstream tasks. Stanford’s foundational report describes this broad-training-and-adaptation pattern. A language model is one kind of foundation model; other models can work with images or multiple modalities. A foundation model is not the entire assistant, and a “base model” is not automatically ready to follow every user instruction.
What Makes a Model a Foundation Model?
Think of a foundation model as a strong base skill set rather than a finished app.
A task-specific model is like training someone only to sort support tickets. It might do that one job well, but it was built for a narrow lane. A foundation model is more like hiring a broadly trained assistant who can read, write, reason over patterns, work with examples, and adapt to different kinds of requests. You still need to brief the assistant, give it the right information, check the output, and put it inside a workflow.
The word "foundation" matters because the model is a starting point. Chatbots, coding assistants, image tools, search features, customer support systems, analytics helpers, and AI agents can all be built on top of foundation models.
The model is not the whole product. The product also includes prompts, interfaces, tools, retrieval systems, safety filters, permissions, monitoring, memory, and human review. A good foundation helps, but the building still matters.
How Foundation Models Work
Foundation models usually follow a pretrain-then-adapt pattern.
- Broad data is gathered: The model is trained on large collections of text, code, images, audio, video, or other data.
- The model learns general patterns: Pretraining helps it learn relationships without needing every example to be hand-labelled.
- The model stores patterns in parameters: Learned behaviour is captured in weights that shape future responses.
- Adaptation turns the base into a useful tool: Teams add prompts, examples, fine-tuning, retrieval, tool access, safety rules, or app logic.
- Inference uses the adapted model: New prompts, documents, images, or requests go through the model to produce outputs.
- Evaluation keeps the system honest: Teams test quality, monitor failures, review safety, and decide where human oversight is needed.
The important point is that the model is reused. Training a large model from scratch is expensive and technically demanding. Reusing a strong base model lets more teams build AI features without repeating the most costly part of the work every time.
How a Foundation Model Becomes a Useful AI Product
- Pre-train: a model developer trains a general model on broad data so it learns reusable patterns.
- Adapt: a business supplies product documents, examples, instructions or additional training for its support task.
- Use: the application retrieves the relevant product page, asks the model to draft an answer and checks the result before a customer sees it.
That sequence separates the reusable model from the application. A product FAQ that changed yesterday is better supplied through current retrieval than assumed to live in a model’s parameters. Fine-tuning may help with repeatable specialised behaviour, but it does not replace current evidence. Stanford’s definition of foundation models centres on broad training followed by adaptation to many tasks. For the next layer, see large language models; for the training process, see model training.
Why Foundation Models Matter
Foundation models changed the economics and workflow of AI development.
Before this pattern became common, many AI systems were trained for one narrow task: classify this image, predict this number, detect this kind of fraud, rank these results. Those models are still useful, but they often need task-specific data, training, evaluation, and maintenance.
Foundation models make a different promise: train a powerful general base once, then adapt it many times.
That matters because it can:
- Reduce the need to build every AI model from scratch.
- Make advanced AI capabilities available through APIs, model hubs, and product platforms.
- Let one model support many use cases, such as chat, summarisation, coding, search, extraction, and document analysis.
- Help small teams prototype AI features faster.
- Shift more of the work from raw model training to evaluation, prompting, retrieval, privacy, product design, and governance.
The trade-off is concentration. If many products depend on the same foundation model, the model's weaknesses can spread too. A biased, unreliable, insecure, expensive, or poorly understood base can quietly shape many downstream systems.
Pre-Training, Adaptation and Evaluation Explained
| Part | What it means | Why it matters |
|---|---|---|
| Broad training data | Large collections of text, code, images, audio, video, or other data | Gives the model patterns to reuse |
| Model architecture | The technical design, such as transformer or diffusion systems | Shapes what data the model can process |
| Parameters or weights | The learned values inside the model after training | Store the model's learned behaviour |
| Pretraining | The large initial training stage | Creates the reusable base capability |
| Adaptation layer | Prompts, fine-tuning, retrieval, tools, safety rules, or app logic | Makes the general model task-ready |
| Inference | Running new input through the model to get an output | This is what users experience when an AI tool responds |
| Evaluation and monitoring | Tests, review, benchmarks, logs, and quality checks | Helps catch errors, drift, bias, and misuse |
The phrase "foundation model" usually points to the base plus its reusable potential. In real products, the surrounding system is just as important as the model itself.
Foundation Model Examples and Applications
Foundation models show up in more places than chatbots.
A conversational assistant may use a language foundation model to answer questions, draft text, analyse files, and help with planning. The model handles much of the language work, while the app adds interface, settings, memory, tools, and safety controls.
A coding assistant can use a foundation model trained on code and natural language. It may explain errors, generate tests, propose refactors, or complete functions. The useful output still needs review because generated code can be wrong, insecure, or out of step with the codebase.
An image generation product may use a visual foundation model to turn text prompts into images, edit parts of a picture, or produce design variations. The product experience depends on prompt controls, safety filters, rights management, and editing tools.
A company assistant can pair a general model with current internal documents. The model drafts the answer; retrieval supplies the relevant policy. The team still needs to check that the answer follows the right policy version.
A multimodal AI system may work across text, images, audio, video, and code. In that case, the foundation model or model family is reused across several input and output types, not only plain text.
Benefits and Limitations of Foundation Models
Foundation models are powerful because they make reuse practical. Their limitations come from the same fact: many tasks may depend on one broad, imperfect base.
| Area | Benefit | Limitation | What to watch |
|---|---|---|---|
| Speed | Teams can build faster | Fast prototypes can hide weak evaluation | Test with realistic inputs before relying on outputs |
| Cost | Reuse can avoid training from scratch | Inference, tuning, hosting, and monitoring still cost money | Track cost per request, latency, and model size |
| Flexibility | One model can support many tasks | General ability does not equal domain expertise | Add context, retrieval, review, or tuning |
| User experience | Natural language makes software easier to use | Ambiguous prompts can produce guessed answers | Design clear workflows, not just a text box |
| Quality | Broad training can produce strong baseline capability | The model can still hallucinate, reflect bias, or miss context | Verify important claims and sensitive outputs |
| Governance | One shared base can be monitored centrally | Shared flaws can affect many apps | Document model choice, risks, data use, and review paths |
The useful middle ground is not "foundation models solve everything" or "foundation models are too risky to use." The right question is whether the model, data, workflow, and oversight match the job.
Foundation Model vs LLM vs Generative AI vs Base Model
These terms overlap, but they are not interchangeable.
| Concept | Best for | Key difference |
|---|---|---|
| Foundation model | A reusable AI base adapted to many tasks | Describes broad training and downstream reuse |
| Large language model | Text and language-like tasks such as writing, coding, summarising, and chat | A major type of foundation model, but not the only type |
| Generative AI | Creating text, images, code, audio, video, or other outputs | Describes what the system does |
| Base model | The underlying pretrained model before extra adaptation | Often the raw starting point for products or fine-tunes |
| Fine-tuned model | A base model adapted with task-specific training | More specialised, but still inherits from the base |
| Task-specific model | A model trained mainly for one narrow job | Less flexible, but often simpler or more reliable |
Keep the layers separate: a foundation model is the reusable base; an LLM works mainly with language; generative AI describes content creation; a product adds the interface, data and controls.
How to Evaluate a Foundation Model for Your Task
When you are evaluating an AI product or planning an AI feature, do not stop at "it uses a foundation model." That is the start of the conversation, not the end.
Ask:
- What foundation model or model family is being used?
- What kind of data was it trained or adapted on, if that is disclosed?
- Is the task handled by prompting, fine-tuning, retrieval, tools, or a mix?
- What private or sensitive data enters the system?
- How are outputs evaluated before users rely on them?
- What happens when the model is uncertain, wrong, slow, biased, or unavailable?
- Can a smaller or more specialised model do the job better?
- Who is accountable for reviewing the output?
Foundation models are most useful when they are treated as capability infrastructure. They are less useful when a team treats the model as a finished strategy.
Common Misconceptions About Foundation Models
Misconception 1: A foundation model is the same as ChatGPT.
ChatGPT is a product. It uses model capability, plus an interface, tools, policies, memory options, account settings, and many product decisions. A foundation model is the reusable model layer beneath products like this.
Misconception 2: Foundation models are only large language models.
Many famous foundation models are LLMs, but the category is broader. Foundation models can work with images, audio, video, code, robotics, scientific data, or several modalities at once.
Misconception 3: A foundation model knows everything it needs.
A broad model still lacks your private context, current documents, internal policies, customer history, and judgement. For serious work, it often needs retrieval, constraints, examples, and review.
Misconception 4: Fine-tuning fixes every weakness.
Fine-tuning can make a model better for a domain or task, but it can also be costly, brittle, or unnecessary. Sometimes a better prompt, better retrieval, or a narrower model is the cleaner choice.
Misconception 5: Reusing a foundation model removes risk.
Reuse can reduce development cost, but it does not remove hallucinations, bias, privacy concerns, security issues, IP questions, or operational cost. It moves the risk into system design and governance.
What a Base Model Can and Cannot Do Alone
The best way to think about a foundation model is simple: it is neither a blank template nor a finished employee. It is a capable base that needs direction, context, constraints, tools, and review.
That is why two products built on similar model capability can feel completely different. One may be a loose chatbot that answers almost anything. Another may be a tightly scoped support assistant that only answers from approved documents. Another may be a coding workflow that reads a repository, proposes changes, runs tests, and asks for approval.
The model matters. The wrapper matters too.
For builders and operators, the practical skill is knowing which layer you are judging. Is the issue the base model, the prompt, the retrieved context, the product workflow, the evaluation process, or the human review step? Better AI work usually starts there.
What to Remember About Foundation Models
- A foundation model is a large reusable AI base trained on broad data and adapted for many downstream tasks.
- The reuse pattern is the point: one strong pretrained model can support many products, workflows, and specialised systems.
- LLMs are a major type of foundation model, but foundation models can also handle images, code, audio, video, and multimodal tasks.
- Foundation models can be adapted through prompting, fine-tuning, retrieval, tools, safety systems, and product design.
- The base model's strengths and weaknesses travel downstream, so evaluation and governance matter.
- A foundation model is not the whole AI product. The surrounding workflow often decides whether the system is useful.
FAQ About Foundation Models
Is ChatGPT a foundation model?
ChatGPT is not just a foundation model. It is a user-facing AI assistant product built around large model capability, plus interface design, tools, safety systems, memory options, account features, and product rules. The underlying model layer is closer to what people mean when they talk about foundation models.
Are all LLMs foundation models?
Most modern large language models are commonly treated as foundation models because they are trained broadly and adapted across many tasks. The terms are still not identical. LLM describes a language-focused model type, while foundation model describes broad training and reuse across downstream tasks.
Is a foundation model the same as generative AI?
No. A foundation model is a reusable model. Generative AI creates new content. A foundation model can power a writing tool, but it can also support classification, search or image analysis without producing a draft.
What is the difference between a foundation model and a base model?
A base model is usually the pretrained starting point before extra tuning or product-specific adaptation. A foundation model is a broader term for a reusable model trained on broad data that can support many downstream tasks. In everyday AI product conversations, the terms often overlap.
Can a foundation model do many tasks without fine-tuning?
Often, yes. A foundation model can handle many tasks through prompting, examples, context, retrieval, and tool use without changing its weights. Fine-tuning is useful when a team needs more consistent behaviour for a specialised domain, format, tone, or task, but it is not always the first step.
Do foundation models learn from every prompt?
Normal inference does not update the model's weights after every prompt. Your input can shape the current response, and product providers may separately use feedback or logs under their own policies, but the immediate act of asking a question is model use, not full retraining.
What are the main foundation model risks?
A shared model can make many products useful, but it can spread the same mistakes across them. Check factual errors, bias, privacy and security in the actual product. Choose the model for the task, test it and keep human review where errors matter.