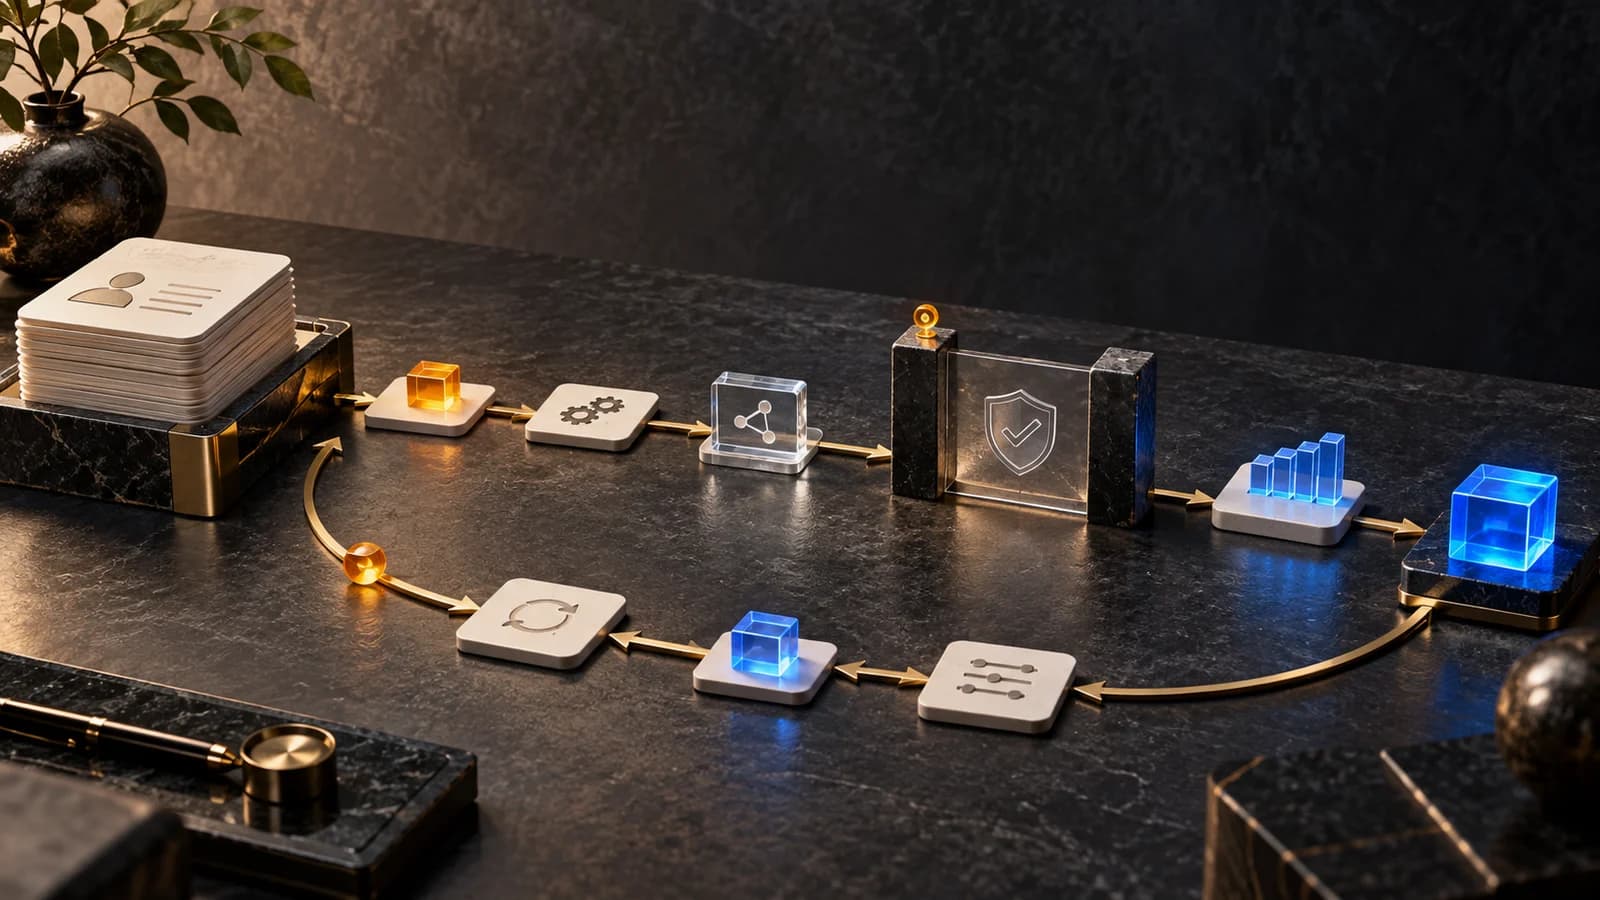
The awkward part of launching a customer-service AI agent often arrives after launch. A refund request reaches the wrong action, a knowledge article is inaccessible, or a new instruction fixes one case and breaks another. Salesforce introduced Agent Optimizer on 21 September to connect those production signals to building and testing in Agentforce. It is available in beta, with human review points rather than a promise of automatic improvement without oversight.
How Salesforce Agent Optimizer works
Salesforce describes two connected places where Optimizer works. In Agentforce Builder, a team can describe a business goal in plain language and have Optimizer propose configuration, simulate conversations and create reusable regression tests. In Agentforce Observability, it can analyse session records, group recurring failures and recommend a change. The proposed fix then moves back into the build-and-test loop.
| Stage | Announced capability | Practical question for the team |
|---|---|---|
| Build | Translate business intent into subagents, actions and instructions. | Are the proposed actions authorised and connected to the right data? |
| Test | Simulate conversations and save cases for later regression checks. | Do tests represent real requests and difficult edge cases? |
| Observe | Group production failures, such as action errors or knowledge gaps. | Are the patterns based on enough representative sessions? |
| Improve | Recommend, build and test a change, with selected review gates. | Who signs off before the change reaches customers? |
The useful idea is a closed loop. A failed conversation becomes a reproducible test; the team changes the agent; the same case runs again alongside older cases. That is more reliable than editing an instruction after reading one unusual transcript. Salesforce’s launch post calls the control over approval points an “autonomy dial.” It says users can require sign-off at every step or allow Optimizer to investigate, build, test and stage work for deployment before review.
The difference between spotting a failure and fixing one
An analytics screen can tell a team that escalations rose. It cannot, by itself, tell whether the cause was a missing knowledge article, a permissions change, a tool error or a policy the agent should never have tried to satisfy. Salesforce is trying to connect those stages: observe a pattern, inspect representative sessions, propose a targeted change and run a test before the next deployment.
This matters because the obvious fix is often wrong. Suppose an agent frequently says it cannot answer a question. Adding more content may seem sensible. But Salesforce's help guidance says to first check whether content already exists but is inaccessible, misconfigured or poorly retrieved. The correct action might be to repair access or search, not to write duplicate answers. Similarly, a cluster labelled “off-topic” may reveal a genuine new customer need or an attempt to use the agent outside its authorised scope. Those require different decisions.
Optimizer output should therefore be treated as a diagnosis to test. Ask it for the sessions behind a pattern, check their traces and confirm whether the suggested cause explains more than one case. This is where the human reviewer adds business context: the software can group conversations, but the team decides which customer outcomes matter and which actions the agent is permitted to take.
A realistic example: repeated refund failures
Suppose customers ask whether a refund has been issued, but the agent often replies that it cannot find the order. Optimizer might cluster those sessions, show a representative trace and suggest that a knowledge action lacks access to the refund-status source. The team should verify that diagnosis in the trace, fix the permission or retrieval path, then run cases for authorised and unauthorised customers. The intended metric is successful, policy-compliant resolution, not just fewer escalations.
Salesforce’s product help recommends reviewing multiple representative sessions before changing an agent and comparing performance signals after deployment. It notes that grouped diagnosis samples sessions rather than reading every one: roughly 100 by default, up to 1,000 per analysis. It also says recent transcripts can take about 15–30 minutes to appear. That makes a “root cause” suggestion a lead to investigate, not a proven diagnosis.
A sensible beta trial for an Agentforce team
Choose one agent with a stable volume of sessions and one costly, repeatable problem. Record a baseline for at least the relevant customer journey: how many requests reach a useful answer, how many escalate, how long resolution takes, and whether quality or compliance suffers. Then identify a failure category with enough examples to inspect. A handful of vivid conversations may make a good story but a poor basis for prioritisation.
Use Optimizer to group the sessions, open traces for representative examples and test its proposed cause against contrary examples. If it suggests a change, save the failing cases as regression tests and add at least one case that should remain unchanged. Review the proposed configuration and any data-access change before staging. After deployment, compare the same metrics and inspect new failures. A lower escalation rate is not automatically a win if the agent now gives confident but incorrect answers.
| Trial stage | Evidence to keep | Stop or rethink if |
|---|---|---|
| Baseline | Volume, resolution, escalation, quality and time period. | The underlying session data is incomplete. |
| Diagnosis | Session IDs, traces and alternative explanations. | The pattern rests on too few or unrepresentative cases. |
| Change | Proposed configuration, approvals and regression results. | A fix expands permissions without a clear need. |
| Follow-up | Same metrics after deployment and newly observed errors. | Improvement is only visible in the test suite, not customer outcomes. |
This trial does not require adopting Salesforce's long-term vision of self-improving agents. It asks whether this beta tool helps one team make one measurable, safe improvement faster than its current process.
| Check before relying on a recommendation | Why it matters |
|---|---|
| Confirm session tracing and optimisation are enabled. | Missing telemetry can make the picture incomplete. |
| Inspect the underlying sessions and timeframe. | A short burst of errors may not be a persistent problem. |
| Run a regression suite before deployment. | A fix for one intent may break another. |
| Keep an accountable reviewer for data access and actions. | Optimising speed must not bypass permissions or business policy. |
Salesforce Agent Optimizer beta: availability and limits
The Salesforce announcement says Agent Optimizer is available now in beta and tells customers to contact their account executive. Salesforce Help lists eligible editions and Einstein add-ons, plus required session-tracing and optimisation settings. Availability therefore depends on the organisation's edition, add-on, configuration and beta terms. The customer examples in the launch post describe broader Agentforce outcomes; they do not independently establish that Optimizer produced those results.
The help page adds two operational limits worth knowing before a demo. Grouped analysis is sampled, so its description of common failure modes may miss rarer but serious cases. Very recent sessions may not be available for detailed review while transcripts are processed. A team investigating a live incident still needs its usual monitoring and escalation path; it should not assume Optimizer will provide a complete or immediate picture.
There is also a commercial and governance question. The launch post invites customers to contact their account executive rather than publishing a simple universal price. Organisations should confirm beta access, data handling, retention, usage costs and the people allowed to approve agent changes in their own environment. Those details can determine whether the workflow is practical at scale even if the demo looks convincing.
For a business already operating agents, the right trial is a measurable one: choose one recurring failure, keep the starting resolution and escalation rates, use Optimizer to investigate, and compare after a reviewed change. Our guide to AI agent harnesses explains the controls around an agent; Optimizer is a tool for improving an Agentforce implementation within that wider operating discipline.
The broader lesson extends beyond Salesforce. Production agents need an operating cycle that turns observed problems into reproducible tests, reviewed changes and measured outcomes. Agent Optimizer may reduce the manual work of that cycle for eligible Agentforce customers. It cannot decide which customer promises, permissions or risk trade-offs a business should make.
Frequently asked questions
Is Agent Optimizer generally available?
No. Salesforce says it is available in beta and directs interested customers to their account executive.
Does it automatically deploy fixes?
Salesforce describes configurable review points, including a mode that stages changes for review. A business should confirm its own approval settings before relying on the workflow.
Does it analyse every production conversation?
No. Salesforce Help says grouped diagnosis uses a sample, about 100 sessions by default and up to 1,000 in one analysis. Exact counts and sampled explanations serve different purposes.